Voice AI agent stack · L1 · 20 min
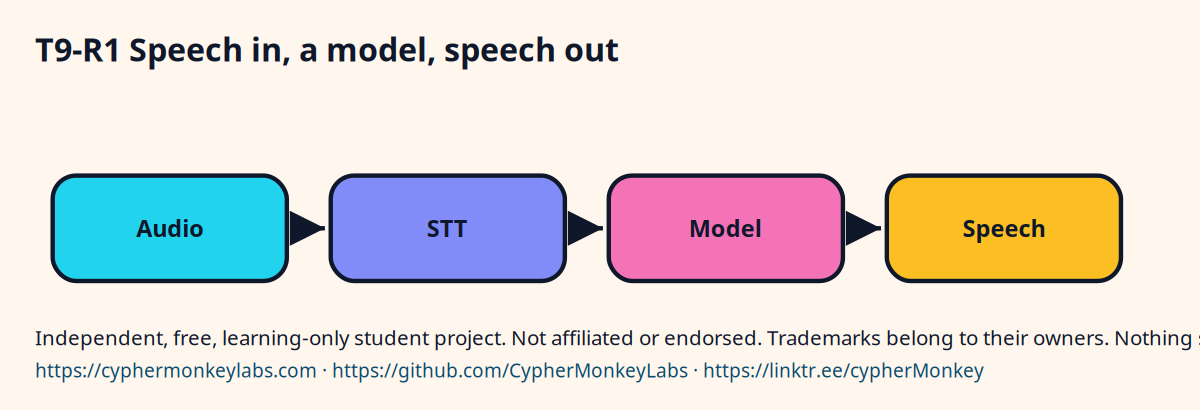
Speech in, a model, speech out
Learn in five minutes
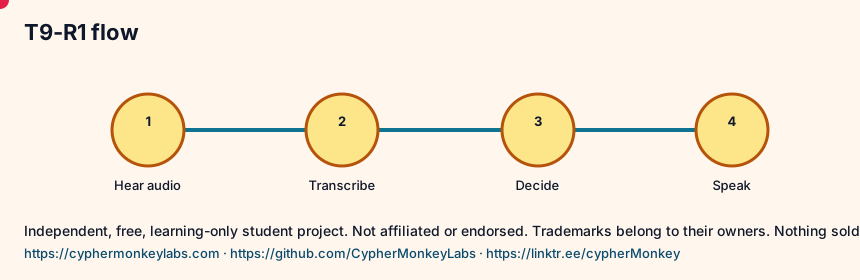
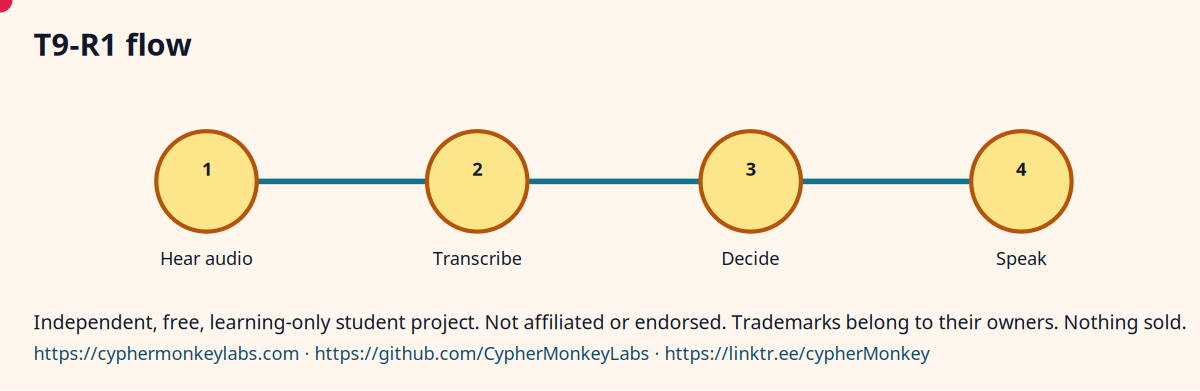
- LiveKit's pipeline page names a cascaded pipeline: speech-to-text, then a language model, then text-to-speech.
- The same page also names turn-based and full-duplex realtime models, which consume and produce speech in one model.
- Pipecat's overview lists a transport, speech recognition, a language model, speech synthesis, and a transport again.
- The Voice overview on docs.x.ai separates Speech to Speech, Text to Speech, and Speech to Text as different APIs.
- Draw the hearing box apart from the language-model box. They are not the same stage.
LiveKit says you can swap a stage in a cascaded pipeline. A realtime model does not give you that split. Say which shape you mean before you compare them.
Visual
Name the boxes
- Write STT, model, and TTS on three cards.
- Write 'one speech-to-speech model' on a fourth card and set it beside the row, not inside it.
- Point at the card your sentence is about.
- If you cannot point, you are mixing the two shapes.
Quiz
Ecosystem
- Cascaded pipeline
- Speech-to-text, a language model, and text-to-speech, in that order, as LiveKit's pipeline page describes it.
Sisters: Speech-to-text, Language model, Text-to-speech, WebRTC, SIP.
A cascaded pipeline and a speech-to-speech model are two shapes the LiveKit docs name. The xAI Speech to Speech API is a hosted speech-to-speech session.
Pin the model id, the voice, and the date you read the docs.
Config
- Write the goal in one sentence.
- Name the input and the allowed output.
- Save the trace next to the result.
Troubleshooting
- The answer looks fluent and is wrong. Check whether a source passage actually contains the claim.
- The loop never stops. Set a step cap and stop when the tool result repeats.
Sources and go deeper
- LiveKit Agents, Pipeline types vendor last checked 2026-10
- Pipecat open source framework vendor last checked 2026-10
- Voice Overview, docs.x.ai vendor The page calls them SpaceXSI Voice APIs, powered by Grok, and separates Speech to Speech, Text to Speech, and Speech to Text. last checked 2026-10