How models work · L2 · 15 min
Sampling
Learn in five minutes
- Temperature and related controls change how peaked the next-token choice is.
- Greedy decoding repeats the top token.
- A higher temperature is not more truthful.
- Stop sequences end a run.
- Record the settings next to the output or the run is not comparable.
Two answers from the same prompt can differ when sampling is not fixed. Freeze the seed or the settings when you are scoring.
Visual
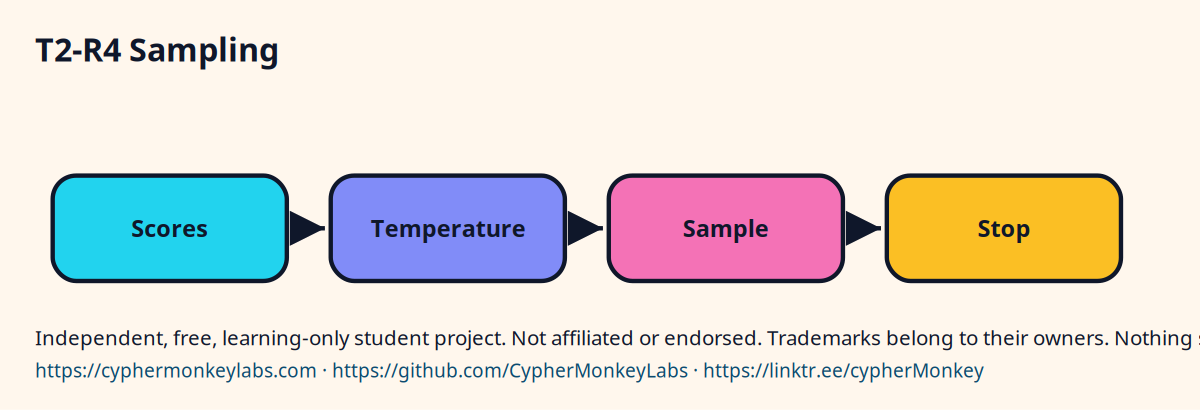
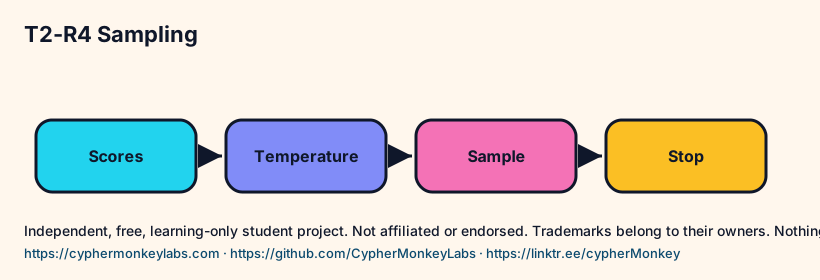
Settings on one card
- Write temperature, max tokens, and a stop sequence on a card.
- Run the same prompt twice if you can, or describe that two samples may differ.
- Do not claim a winner without both settings.
Quiz
Ecosystem
- Temperature
- A sampling control. It is not a truth dial.
Sisters: Tokenizers, Transformers, Decoding, Model cards.
The same next-token idea sits under chat, voice, and tool calls.
Pin a model id when you leave the toy explanations.
Config
- Write the goal in one sentence.
- Name the input and the allowed output.
- Save the trace next to the result.
Troubleshooting
- The answer looks fluent and is wrong. Check whether a source passage actually contains the claim.
- The loop never stops. Set a step cap and stop when the tool result repeats.
Sources and go deeper
- Brown and co-authors, Language Models are Few-Shot Learners, 2020 paper last checked 2026-10
- Large language model — Wikipedia wikipedia last checked 2026-10