Voice AI agent stack
Voice stack
Speech in, a model, speech out, and the network that carries the audio. This lab places no call and sends no audio.
The cascaded row
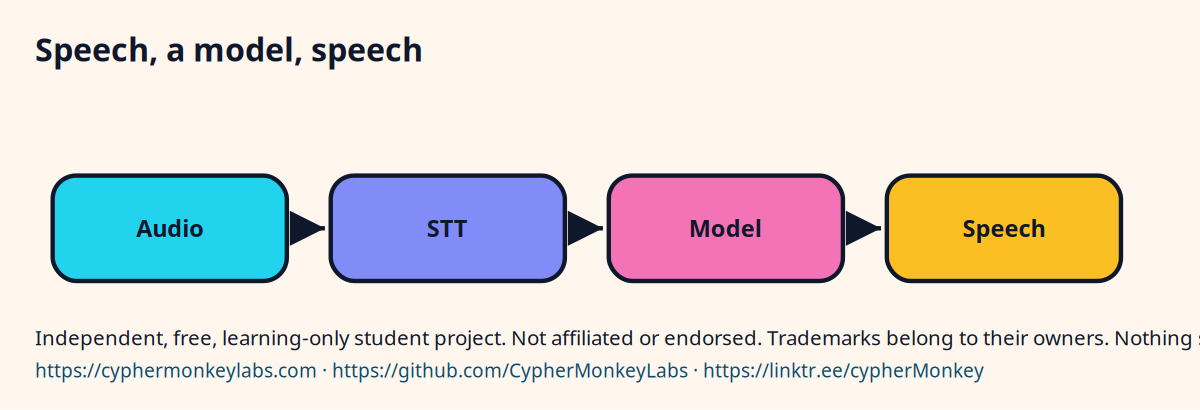
Diagram SVGDiagram PNGDiagram HTMLTrack map HTML
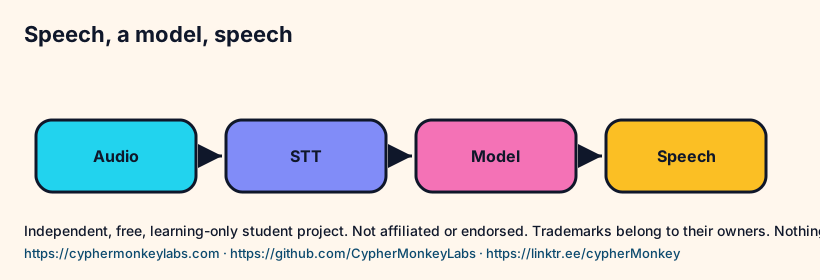
LiveKit's pipeline page names a cascaded pipeline as speech-to-text, then a language model, then text-to-speech. A realtime model, on that page, consumes and produces speech in one model. Pipecat's overview lists a transport, speech recognition, a language model, speech synthesis, and a transport again.
Sort the cascaded order
Put the first voice room's flow back in order. A speech-to-speech model is a different shape. It does not sit inside this row.
- Speak
- Decide
- Transcribe
- Hear audio
Match the words
Rooms
- Speech in, a model, speech out
- Turn-taking and barge-in
- Latency budgets you label
- Telephony and WebRTC
- LiveKit Agents and Pipecat
- A hosted voice agent, from the xAI docs
Latency sentences stay attached to the page that wrote them. This lab states no service-level agreement and no price.
Sources and go deeper
- LiveKit Agents, Pipeline types vendor last checked 2026-10
- Pipecat open source framework vendor last checked 2026-10
- Voice Overview, docs.x.ai vendor The page calls them SpaceXSI Voice APIs, powered by Grok, and separates Speech to Speech, Text to Speech, and Speech to Text. last checked 2026-10
- LiveKit Agents, Turns overview vendor last checked 2026-10
- Speech to Speech, docs.x.ai vendor The page title is Speech to Speech. The body names the Grok Speech to Speech API and also calls the site SpaceXSI Docs. last checked 2026-10
- Python 3 tutorial vendor last checked 2026-10
- W3C, WebRTC Recommendation, 13 March 2025 spec last checked 2026-10
- WebRTC — Wikipedia wikipedia last checked 2026-10
- RFC 3261, SIP: Session Initiation Protocol spec last checked 2026-10
- Pipecat, Pipeline and frame processing vendor last checked 2026-10